· Updated
Running LLMs Locally with LM Studio: Requirements & Setup
SEO consultant & Google Ads specialist
LM Studio is a free desktop app for downloading and running large language models (LLMs) locally, on your own computer. No account, no API key, and no internet connection is required once a model is downloaded. Since July 2025 it’s also free to use at work, not just at home.
This guide covers what hardware you need to get decent performance, how to get your first model running, and what to do when LM Studio says a model is too large for your machine. It is now (re)written for LM Studio 0.4 (October 2026).
Why run an LLM locally?
- Privacy: Prompts and documents never leave your computer.
- Cost: No subscription or per-token billing. The only cost is hardware and electricity.
- Offline use: Works on a plane, on a locked-down network or anywhere else without a connection.
- Experimentation: Hundreds of open-weight models to test side by side.
Unless you have very powerful hardware with lots of VRAM and/or unified RAM, however, you need to set your expectations accordingly.
A model that fits on a laptop will never be comparable to frontier models from OpenAI or Anthropic. Local models can still be good at summarising, rewriting, drafting, basic coding, and answering questions about documents. They are generally weak at complex reasoning and have no knowledge of anything after their training cutoff.
LM Studio system requirements
| Mac | Windows | Linux | |
|---|---|---|---|
| Processor | Apple Silicon (M1 or newer) | x64 with AVX2, or ARM (Snapdragon X) | x64 or ARM64 |
| Operating system | macOS 14 Sonoma or newer | Windows 10/11 | Ubuntu 20.04 or newer (AppImage) |
| RAM | 16 GB recommended, 8 GB works for small models | 16 GB recommended | 16 GB recommended |
| GPU | Integrated (uses unified memory) | 4 GB+ dedicated VRAM recommended | 4 GB+ dedicated VRAM recommended |
Source: LM Studio system requirements, October 2026.
Does LM Studio run on Intel Macs?
No, there is no Intel build. LM Studio only supports Apple Silicon Macs (M1, M2, M3, M4, M5, M6, and later). On an Intel Mac, Ollama is the simplest alternative. It runs on the CPU only, so expect slow replies.
What is AVX2 and do I have it?
AVX2 is a set of CPU instructions that LM Studio needs on x64 Windows and Linux machines. If your PC is less than ten years old, you almost certainly have it. Practically all Intel processors from the Haswell generation (2013) onwards and AMD processors from Ryzen (2017) onwards support it.
How much RAM and VRAM do you need?
This is the single most important requirement and the reason why memory is extremely expensive right now. A rough rule: a model compressed (quantized) to 4-bit (Q4) takes a little over half a gigabyte per billion parameters. You also need extra room for the conversation itself (the context).
| Memory (RAM on Mac, VRAM on PC) | Realistic model size |
|---|---|
| 8 GB | Up to about 4B parameters |
| 16 GB | 7–9B comfortably, ~20B at a stretch |
| 24–32 GB | 14–32B |
| 64 GB and up | 70B-class models and large mixture-of-experts models |
On a Mac, the GPU shares memory with the rest of the system, so a 16 GB Mac can’t give all 16 GB to the model. On a PC, a model that doesn’t fit entirely in VRAM can be split between the graphics card and system RAM, but this will be noticeably slower.
Download size
The LM Studio app itself is just a few hundred megabytes. The models are what take up space. A small model is 2–5 GB, a mid-sized 10–20 GB, and the largest ones can run to well over 100 GB.
Installing LM Studio
- Download the installer for your platform from lmstudio.ai. The download page also offers Bionic, a separate agent app (see below). For this guide, you want LM Studio.
- Run the installer (Windows), drag the app to Applications (Mac), or make the AppImage executable (Linux).
- Start LM Studio. The first launch offers to download a recommended (small) starter model, which is a good way to check that everything works.
If you want to run LM Studio on a server without a screen, there’s also a headless version called llmster, controlled from the terminal with the lms command.
Downloading your first model
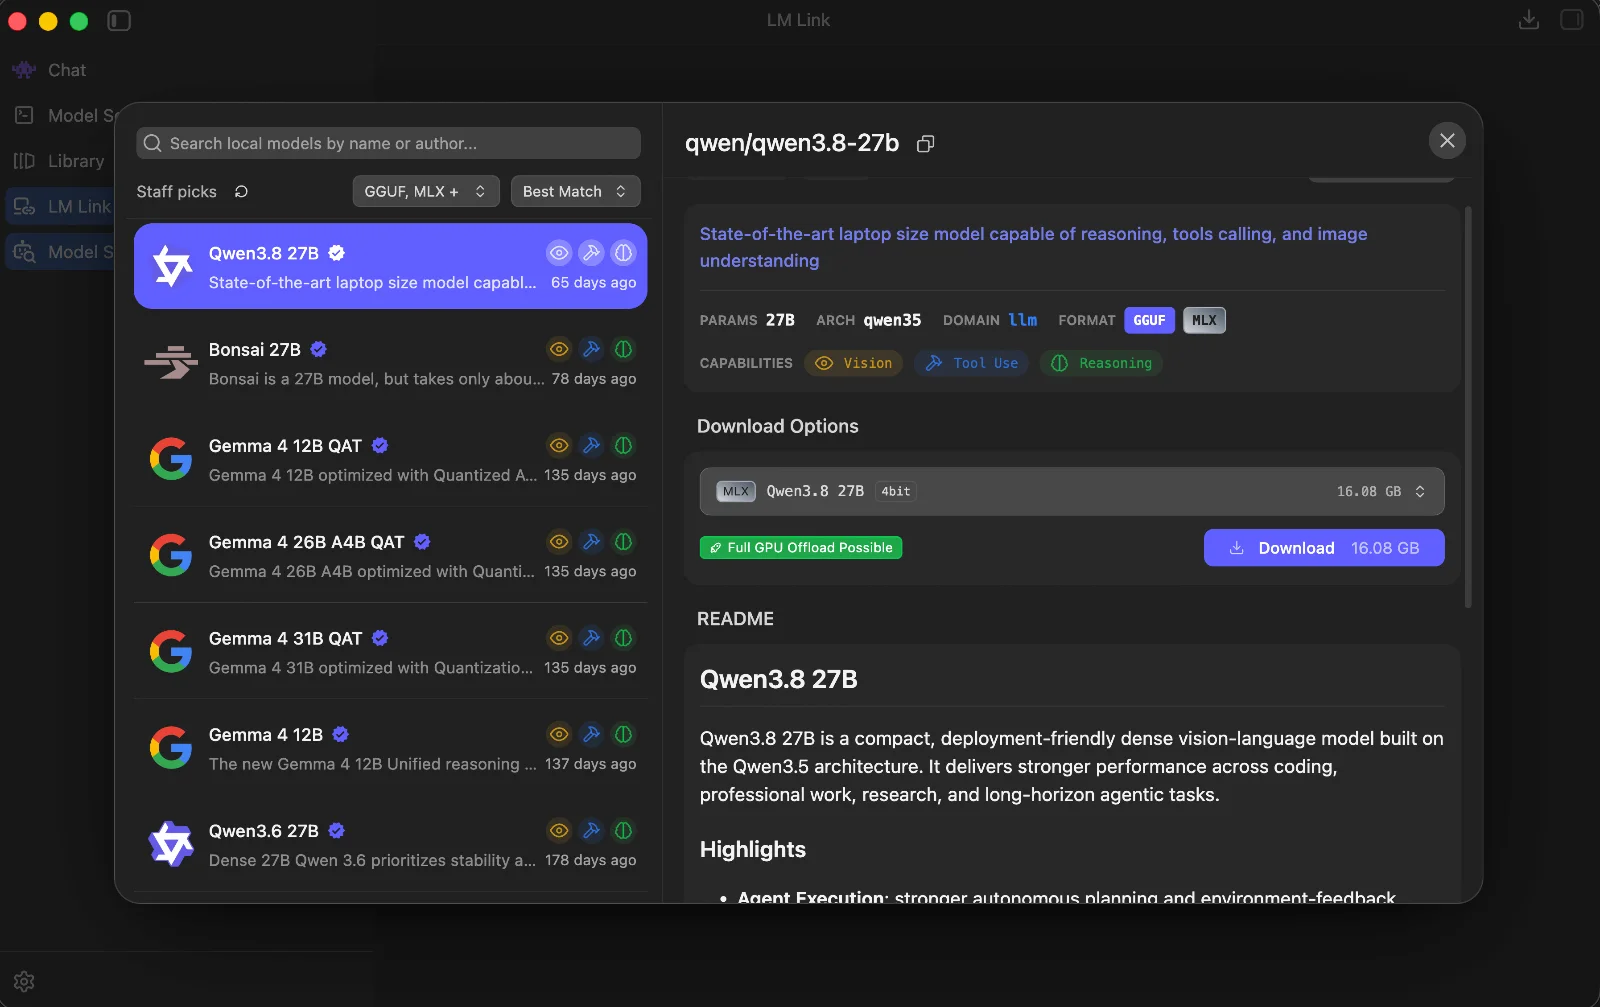
Open Model Search in the left sidebar to browse and search for models. Without a search term you get LM Studio’s staff picks, which is a good place to start. You can also search by name, e.g. “Qwen”, “Gemma” or “gpt-oss”. Select a model to see its download options with file sizes, and a green Full GPU Offload Possible label if it fits entirely in your GPU memory.
A few things worth knowing when you choose:
- Start small. A 4–9B model on a 16 GB machine gives fast replies and leaves room for context. Move up once you know what your hardware can handle.
- Quantisation: The same model is usually offered in several versions, such as Q4_K_M, Q6_K and Q8_0. Lower numbers mean smaller files and also a loss in quality as size goes down. Q4_K_M is often seen as a reasonable compromise between size and capability.
- GGUF or MLX: GGUF files run everywhere. On a Mac you’ll also see MLX versions, which are built for Apple Silicon and usually run faster.
- Popular choices: At the time of writing, the Qwen and Gemma families and OpenAI’s open-weight gpt-oss-20b are among the most downloaded (though not necessarily the best for your particular use case).
- Local or cloud: LM Studio’s model catalogue now also lists cloud models, which run on LM Studio’s servers and are paid. Check that the model you pick is a local download if you want everything to stay on your machine.
What “likely too large for this machine” means
When you browse models, LM Studio estimates whether each one fits in your memory. If it doesn’t, the download options show a red Likely too large label instead of the green one.
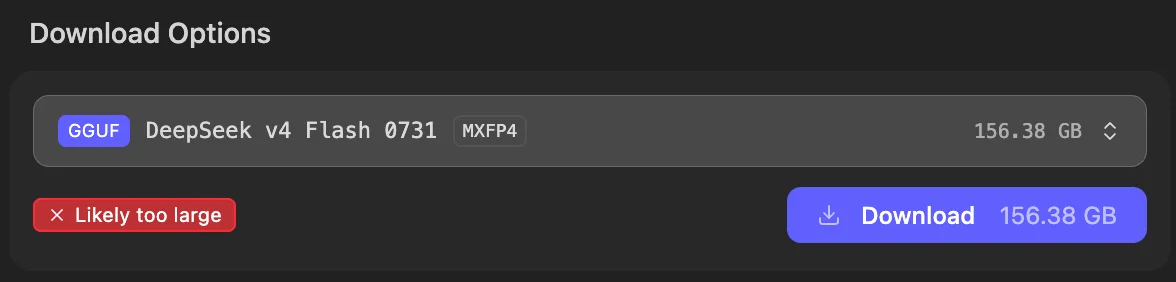
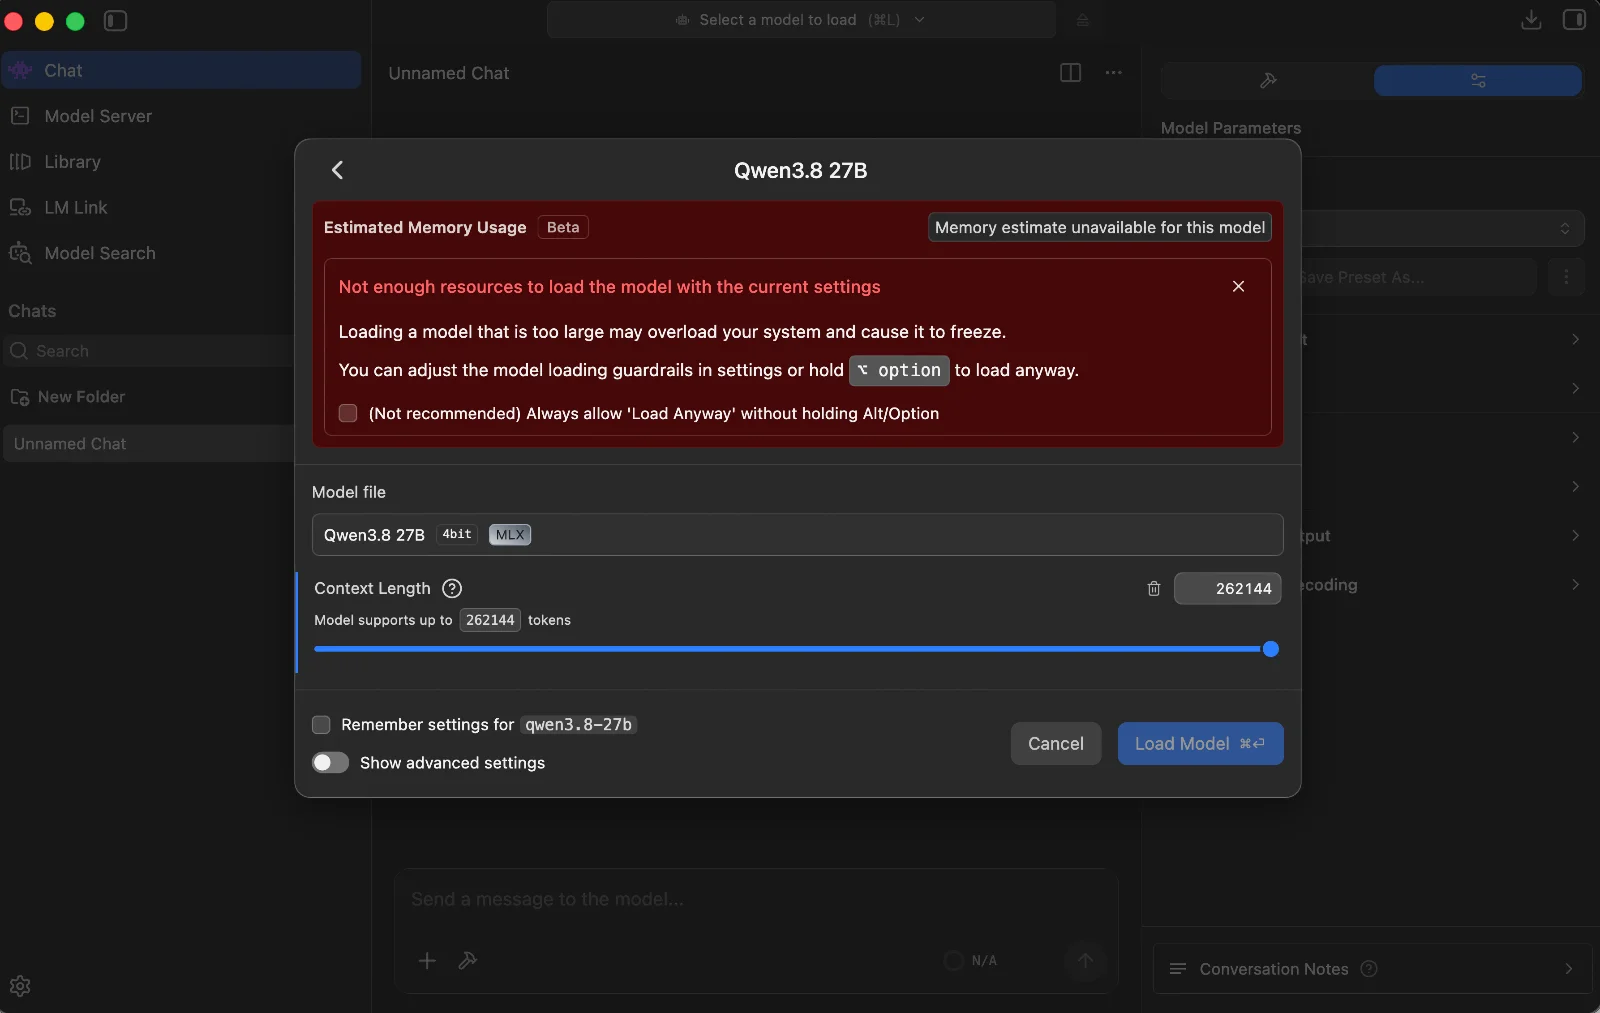
You can still download the model, but when you try to load it, LM Studio stops you with Not enough resources to load the model with the current settings.
It’s only an estimate, but it’s usually about right. You have four choices:
-
Pick a smaller quantisation of the same model, for example at Q4_K_M instead of Q8_0.
-
Pick a smaller model, for example 8B instead of 14B.
-
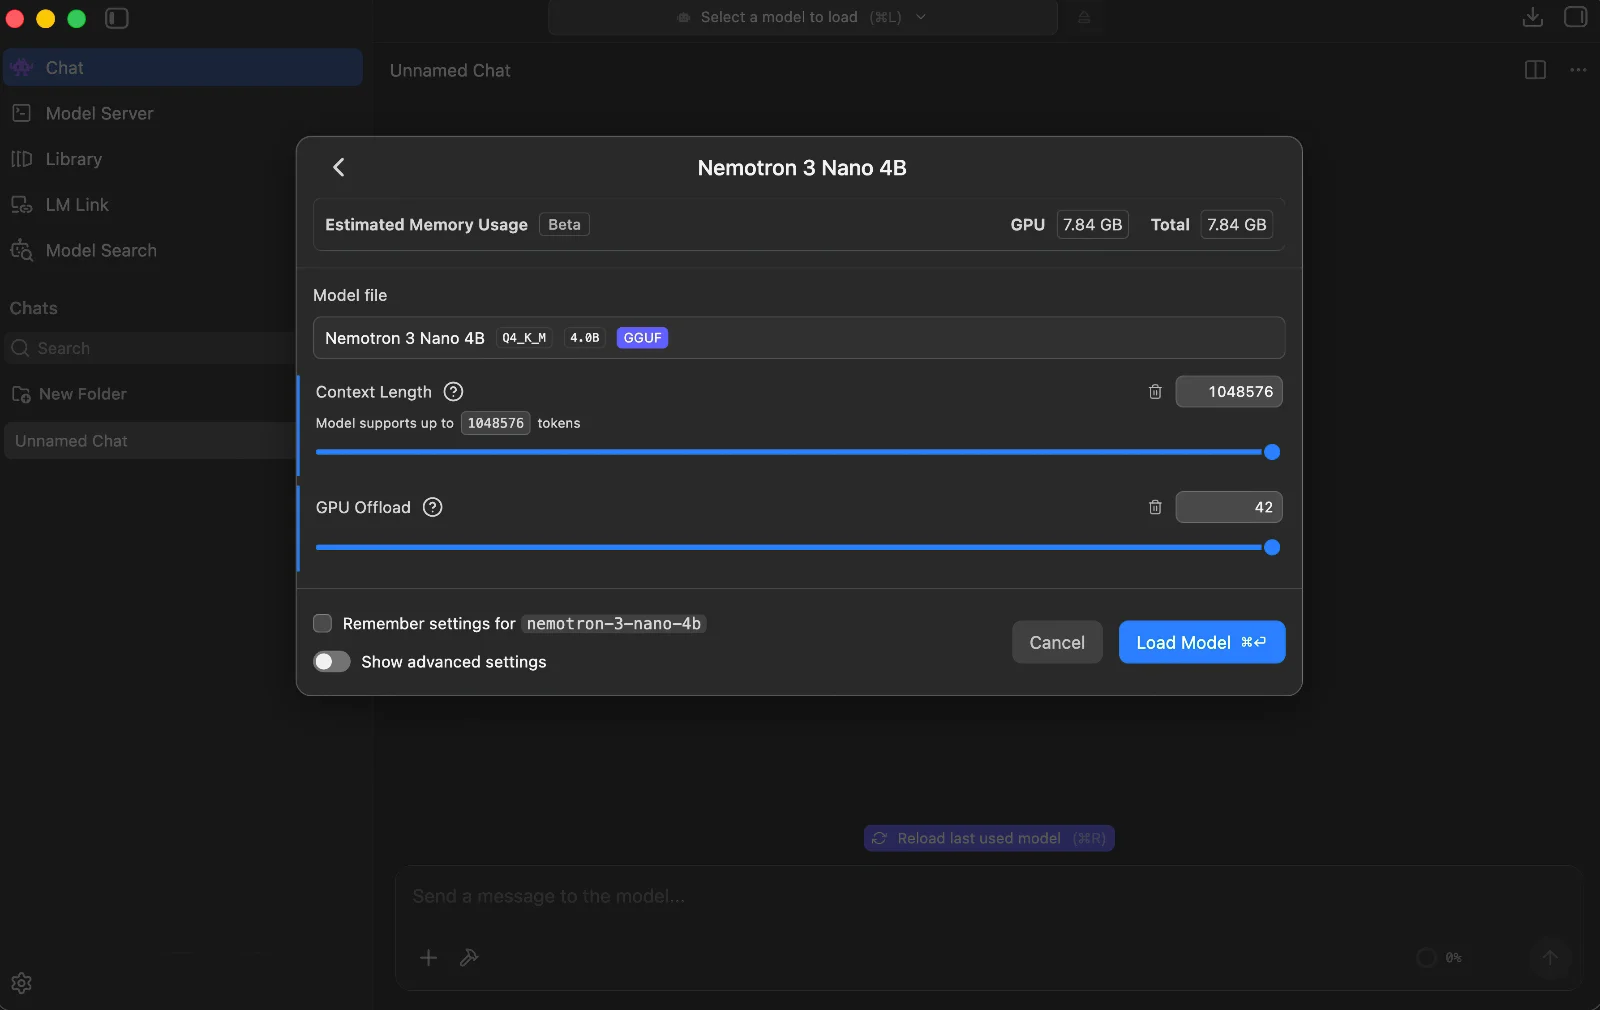
Reduce the context length in the load dialog. A long context window reserves a lot of memory on its own, and the dialog shows the estimated memory usage as you move the slider. Keep in mind, however, that small context windows make the LLM perform worse in longer-running, complex tasks.
-
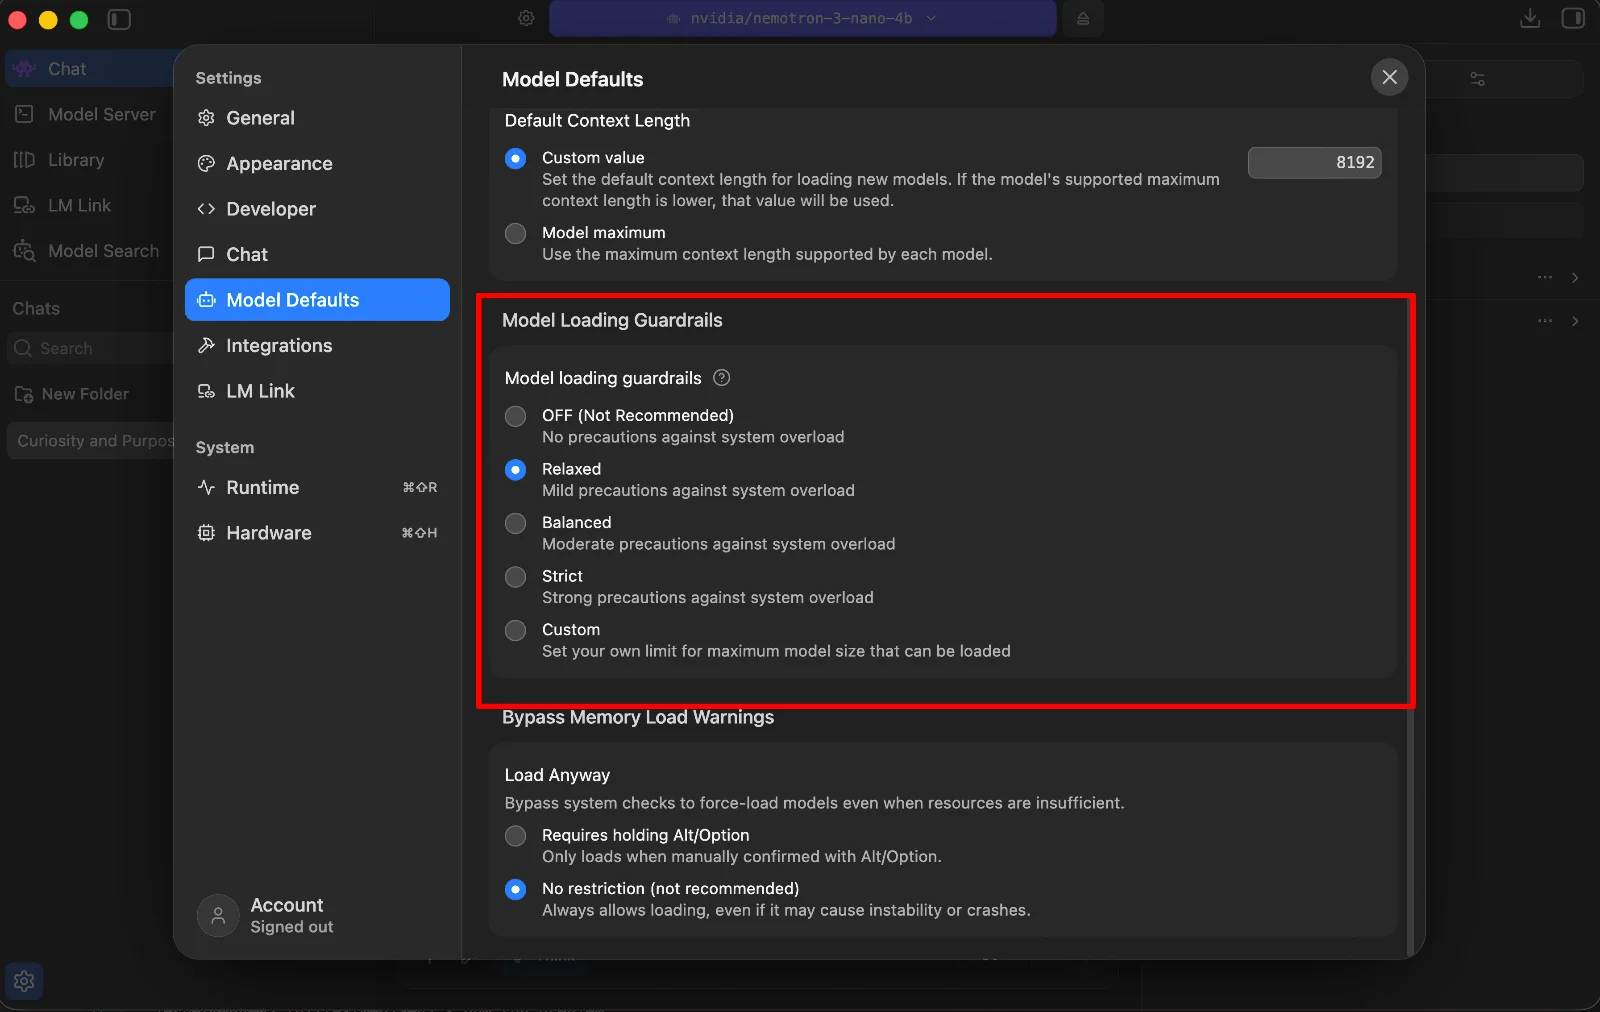
Loosen the guardrails. Open settings (the gear icon at the bottom left) and go to Model Defaults > Model Loading Guardrails. The options are Off, Relaxed, Balanced, Strict and Custom. To get past the block for a single model, hold Alt/Option when you click Load Model. Either way, if the model really doesn’t fit, your computer could slow to a crawl or freeze. Try not to run memory-heavy apps (like Chrome with 70 browser tabs) in the background.
If a model loads but the replies are extremely slow, or outputs nonsense, it’s usually the same problem: the model is too heavy for your hardware.
Chatting and useful settings
Go to Chat in the sidebar and pick a model in the selector at the top of the window. Wait for it to load, then type as you would in ChatGPT or Claude. Below each reply, LM Studio shows how fast the model generated it (tokens per second), which is a quick way to compare models on your hardware.
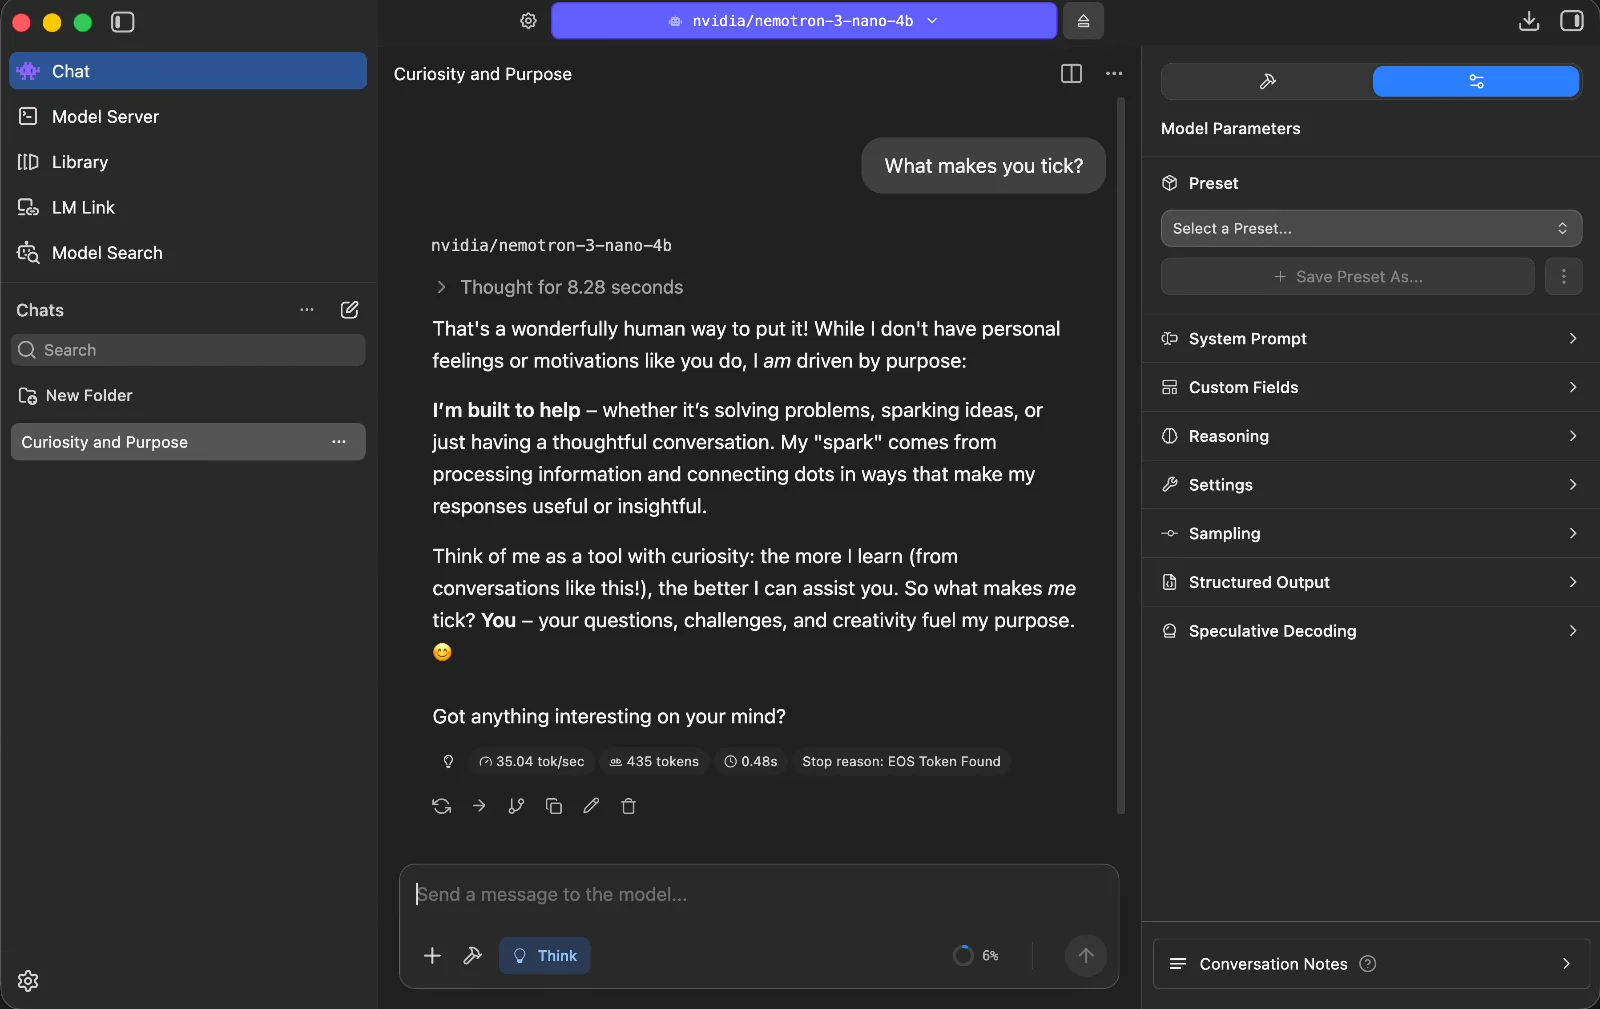
Settings worth knowing about (most are in the Model Parameters panel on the right):
- System prompt: Standing instructions for the model, such as “Answer in Swedish” or “You are an editor who shortens texts”.
- Context length: How much of the conversation the model remembers. Longer uses more memory but also makes it more versatile.
- GPU offload: How much of the model runs on the graphics card. For the best possible performance, this should be all of it.
- Documents: You can attach PDFs, Word docs, and text files. Short documents are added in full; long ones are searched, and only the relevant passages are given to the model (RAG).
You can also run two chats side by side with Split View and export conversations to PDF, Markdown or plain text.
Beyond the chat window
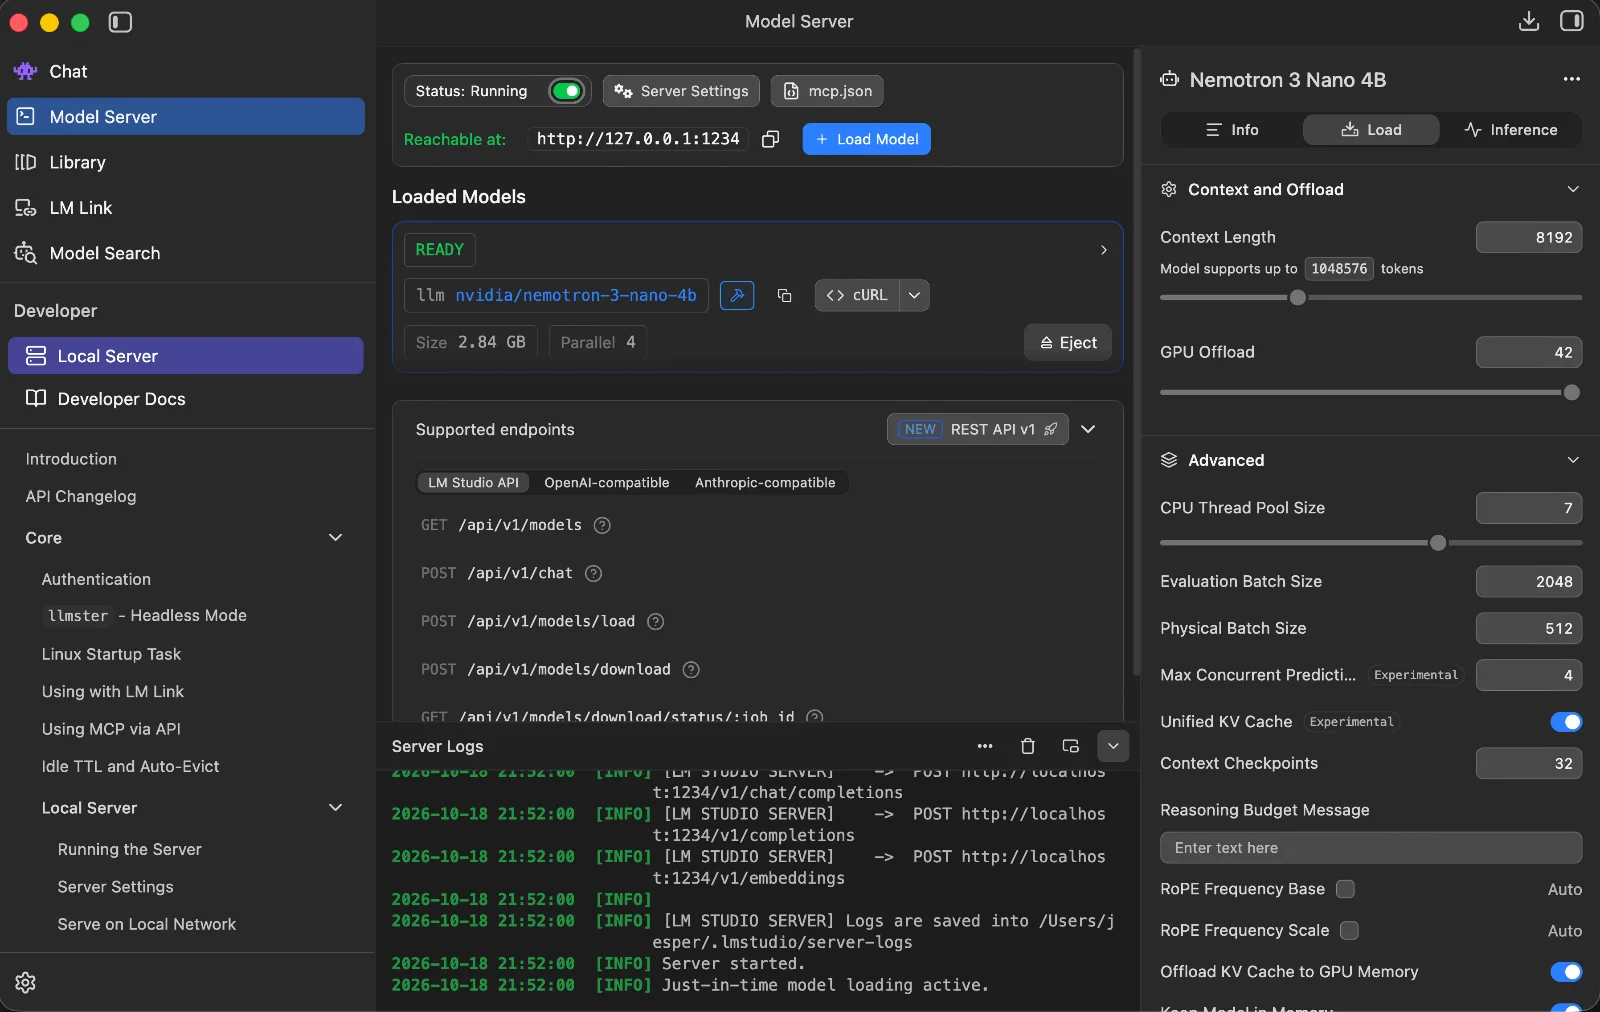
LM Studio can also act as a local AI server. Under Model Server in the sidebar you start a server that, besides LM Studio’s own API, offers OpenAI- and Anthropic-compatible endpoints. Apps and scripts written for those services can use your local model instead, often by changing a single URL. LM Studio also supports MCP servers, which let the model use external tools.
What about LM Studio Bionic?
In July 2026, the company behind LM Studio released Bionic, a separate app for Mac and Windows. Where LM Studio is a place to download, test and chat with models, Bionic is an agent: it works in your project folders, edits code with inline diffs, handles PDFs, spreadsheets and slide decks, and can search the web.
Bionic doesn’t replace LM Studio. Local models in Bionic run on the same LM Studio engine, and LM Studio is still where you go for detailed settings like context length and GPU offload. The main difference is that Bionic can also use larger open models hosted in LM Studio’s cloud. That requires an account and is paid, but LM Studio says cloud requests aren’t stored or used for training.
If you just want to run a model locally and chat with it, LM Studio is all you need. If you want a local alternative to agent tools like Codex or Claude Code, Bionic is worth a look.
LM Studio vs Ollama
Ollama is the other big name in local LLMs. Both run the same open-weight models on the same hardware, but they’re built for different users.
| LM Studio | Ollama | |
|---|---|---|
| Built around | Desktop app | Command line and background service |
| Source code | Closed (free to use) | Open source (MIT) |
| Finding models | Built-in search across Hugging Face | Ollama’s own model library, plus GGUF files from Hugging Face |
| Settings | Visual sliders for context length, GPU offload etc. | Commands and config files (Modelfiles) |
| Intel Mac | Not supported | Works, CPU only |
| Local API | Yes, OpenAI-compatible | Yes, OpenAI-compatible |
Ollama also has a simple chat app for Mac and Windows, but its strength is running quietly in the background and serving models to other apps, scripts and coding tools.
Choose LM Studio if you want to browse, test and compare models without touching the terminal, and see right away whether a model fits in your memory.
Choose Ollama if you mainly want a model available to other software, prefer the command line, or are on an Intel Mac.
You don’t have to choose. LM Studio is a good place to find a model that works on your machine, and Ollama is a good way to keep it running.
Can LM Studio run Stable Diffusion?
No. LM Studio runs language models, including vision models that can read images, but it can’t generate images. For that you need a separate tool. See my guide on running Stable Diffusion locally.
Summary
LM Studio is still the easiest way to run an LLM on your own computer. The two things that decide how well it works are an Apple Silicon Mac or a PC with AVX2, and enough memory for the model you want. With 16 GB you can run fairly capable 7–9B models today, even if none of them are comparable to frontier models.